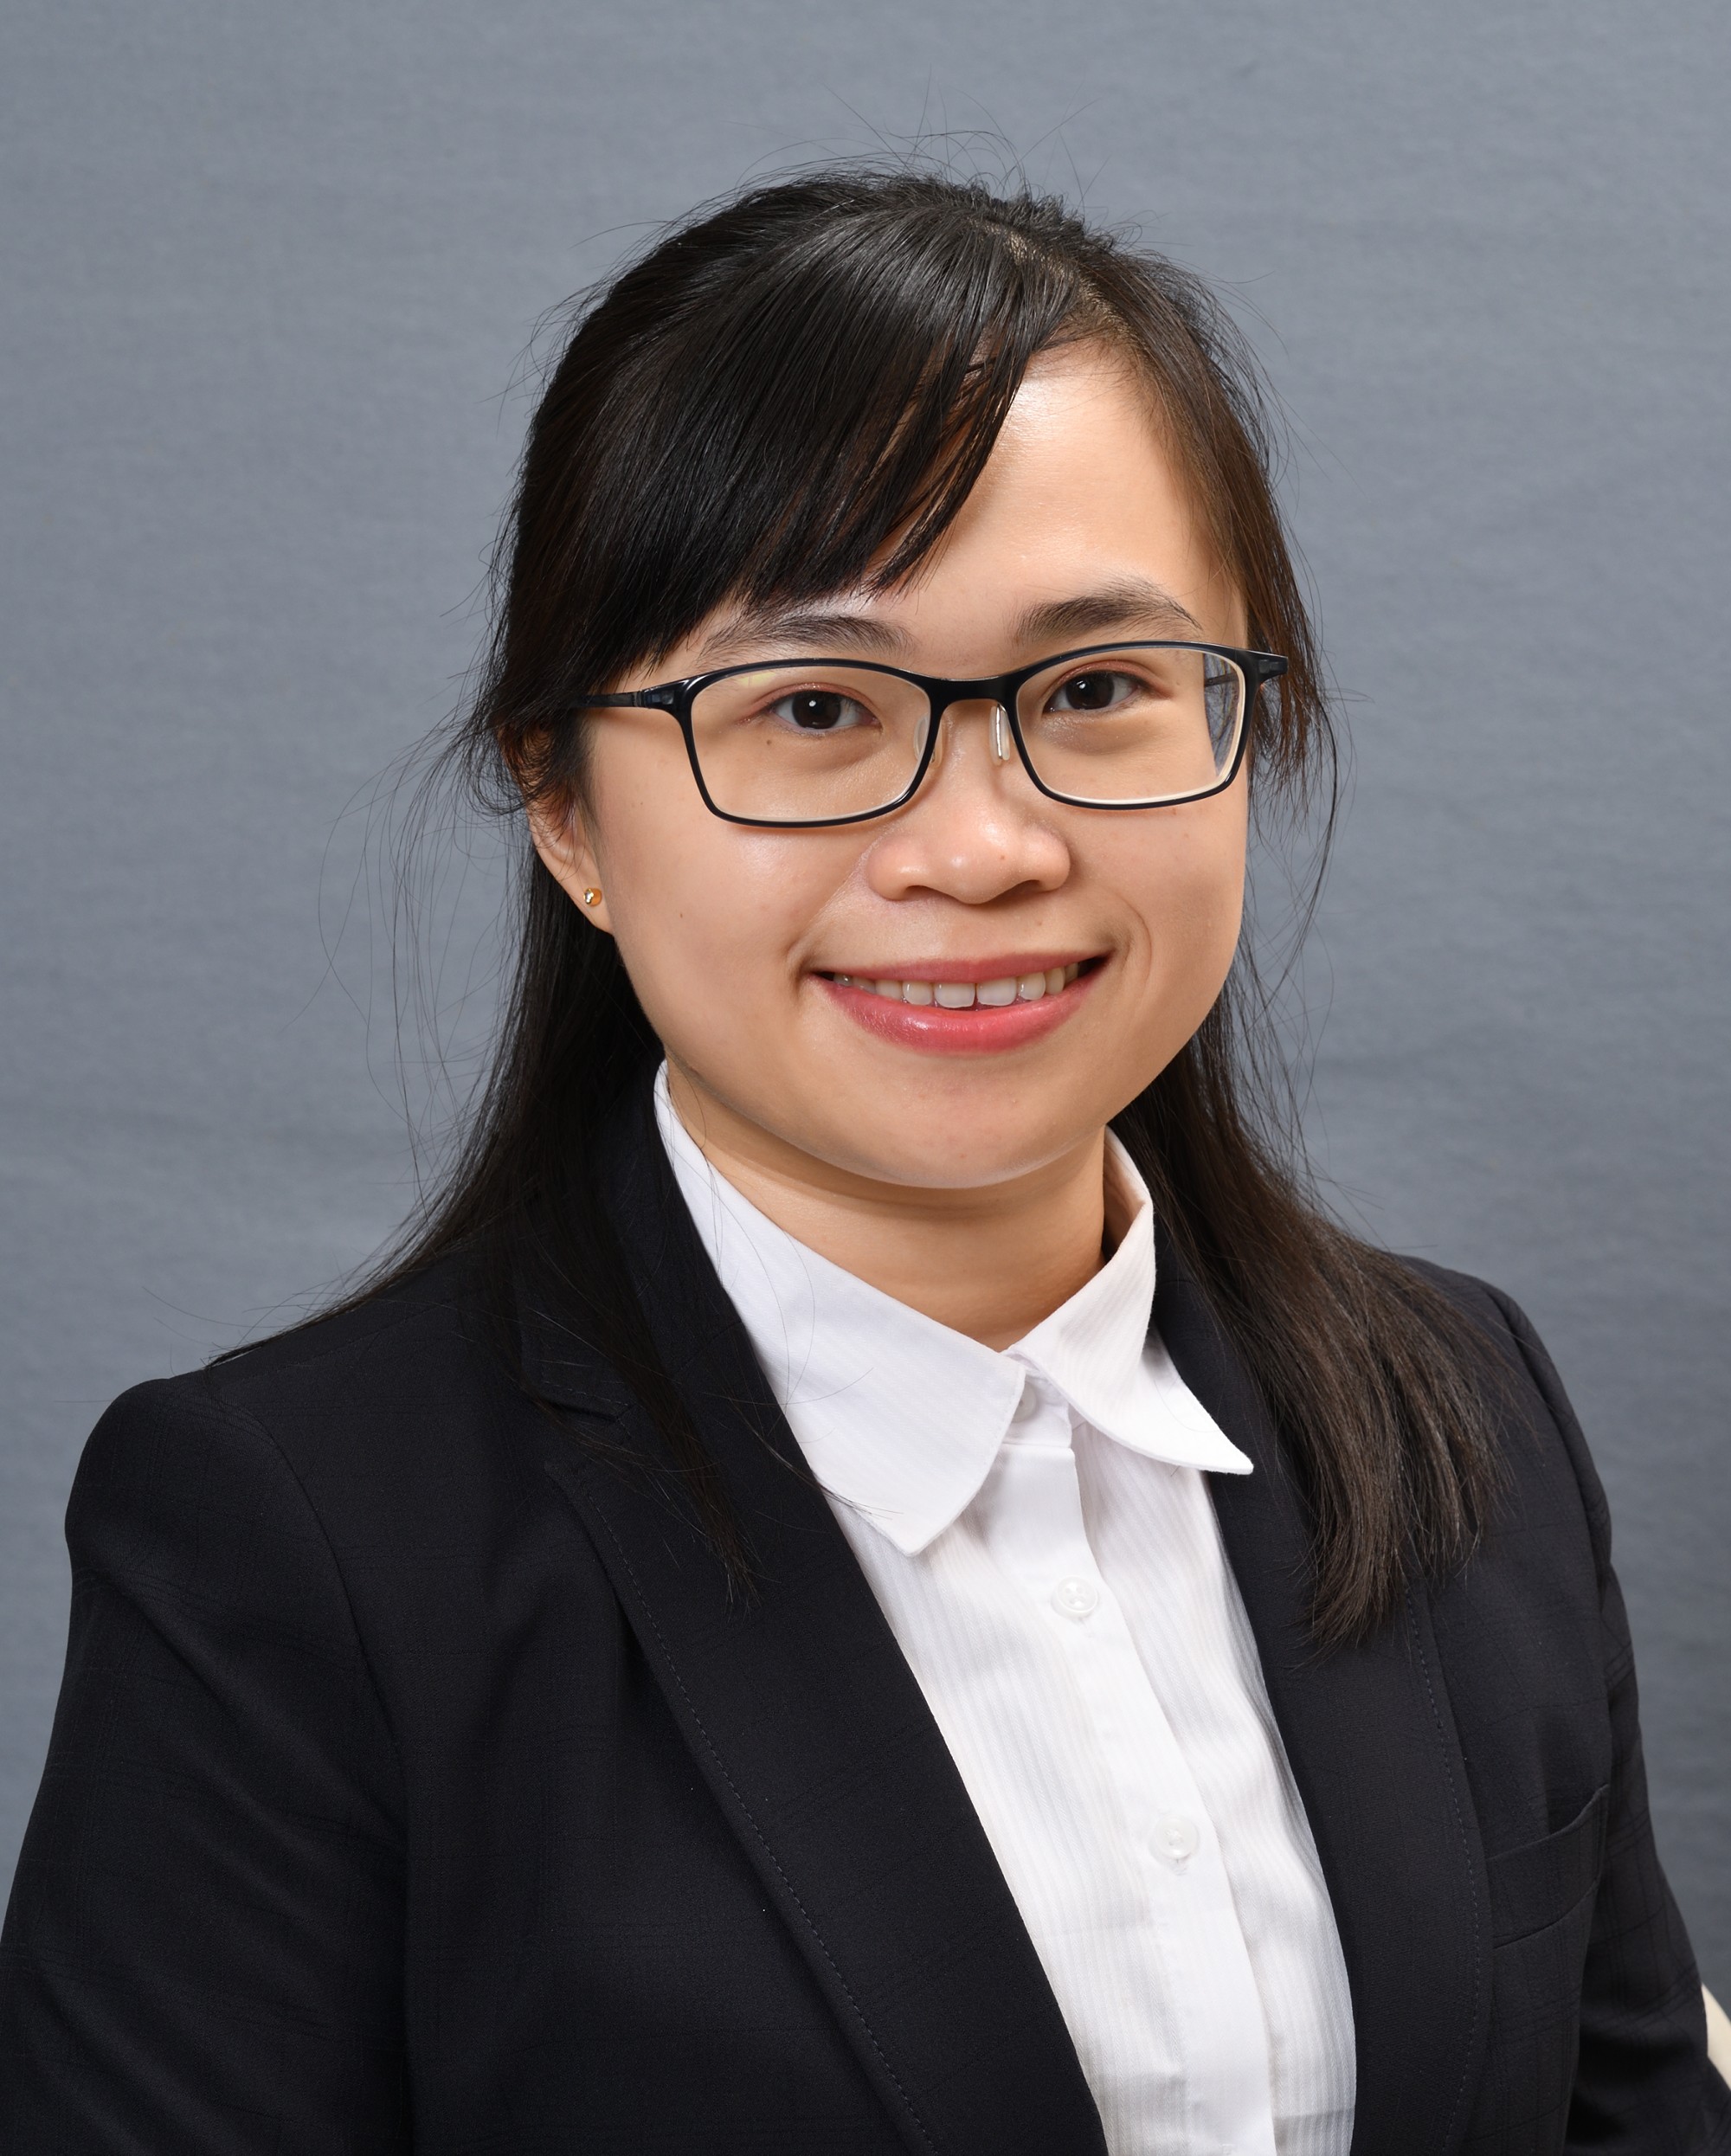
Hi, I'm Candy! I am a senior lecturer at School of Information Science, Japan Advanced Institute of Science and Technology (JAIST). My primary research interests are speech signal processing, machine learning, and social signal processing (SSP). My Ph.D. thesis focuses on privacy preservation and secure speech communication. In addition to primary research, I also carried out a research project on personality traits and communication skills modeling with Prof. Shogo Okada. I obtained my Ph.D. and M.S. degrees in Information Science, JAIST, advised by Prof. Masashi Unoki.
Research interests: Speech and language processing, acoustic phonetics, trustworthy AI, human-computer interaction.
News
I attended APSIPA ASC 2026 in Bangkok, marking my seventh year participating in this conference. Two of my co-advised students presented their papers this year. It was an especially meaningful event for me, as I was honored to be one of invited speakers for the Women in APSIPA session—a wonderful moment to reflect on my growth within this community. I also had a great time catching up with fellow alumni and colleagues from my former supervisor's lab in Thailand.
I recently attended the ACM ICMI 2026 conference in Naples, Italy, for the first time. The conference featured a wide range of fascinating, multidisciplinary research, and its close-knit community made it easy to engage with fellow researchers. It was a very productive trip, highlighted by meeting several online collaborators in person for the first time.
Three of our papers were recently presented at Interspeech 2026—including one resulting from our collaboration with Education Testing Service (ETS) (Privacy vs. Performance: Assessing Communication Utility of Anonymized Voice Features), one based on our student's master's thesis (Adaptive Multimodal Expert Specialization by Meta-Learning for Spoken English Assessment), and one presented at the SPSC Symposium (RocknRiver: Multilingual Speaker Anonymization System for Voice Privacy 2026 Challenge). Although I was unfortunately unable to attend in person this time, I am proud to see our work shared with the community.
Congratulations to Ms. Satida Ruengsurat on the acceptance of our paper, Attacking Voice Anonymization Systems with Composite Metric Learning, at IEEE WIFS 2026! This work originated from her minor research project.
My co-advised students presented four papers covering deepfake detection, speech watermarking, and speech intelligibility prediction at the ASJ Autumn Meeting held at the Kanazawa Institute of Technology (KIT) in Ishikawa. It was a productive meeting and a wonderful opportunity to connect with local speech processing researchers.
Ms. Xiajie Zhou shared our work, Spectro-Temporal Modulation Analysis for Lyric Intelligibility Prediction, at ASJ HCOM in Sendai.
Our paper RocknRiver: Multilingual Speaker Anonymization System for Voice Privacy 2026 Challenge has been accepted for presentation at the Security and Privacy in Speech Communication (SPSC) Symposium 2026.
We are pleased to announce that our research paper, Audio-Guided Visual Selection for Efficient Multimodal Fusion via a Discrete Variational Autoencoder, has been accepted for publication in Information Fusion!
Our papers Dual-Stream EAT-XLSR: A Cascade Framework for Component-Aware Audio Deepfake Detection and MIF: Multi-view Interaction Framework for Speech and Environment Sound Deepfake Detection have been presented by our students, at the 2026 IEEE International Conference on Multimedia and Expo (ICME 2026), Bangkok, Thailand, July 5-9, 2026.
Excited to share that our paper, From Detection to Mechanism Analysis: Interpretable Multimodal Concept Interactions in Gesture Pragmatics, have been accepted for publication in the ACM ICMI 2026!